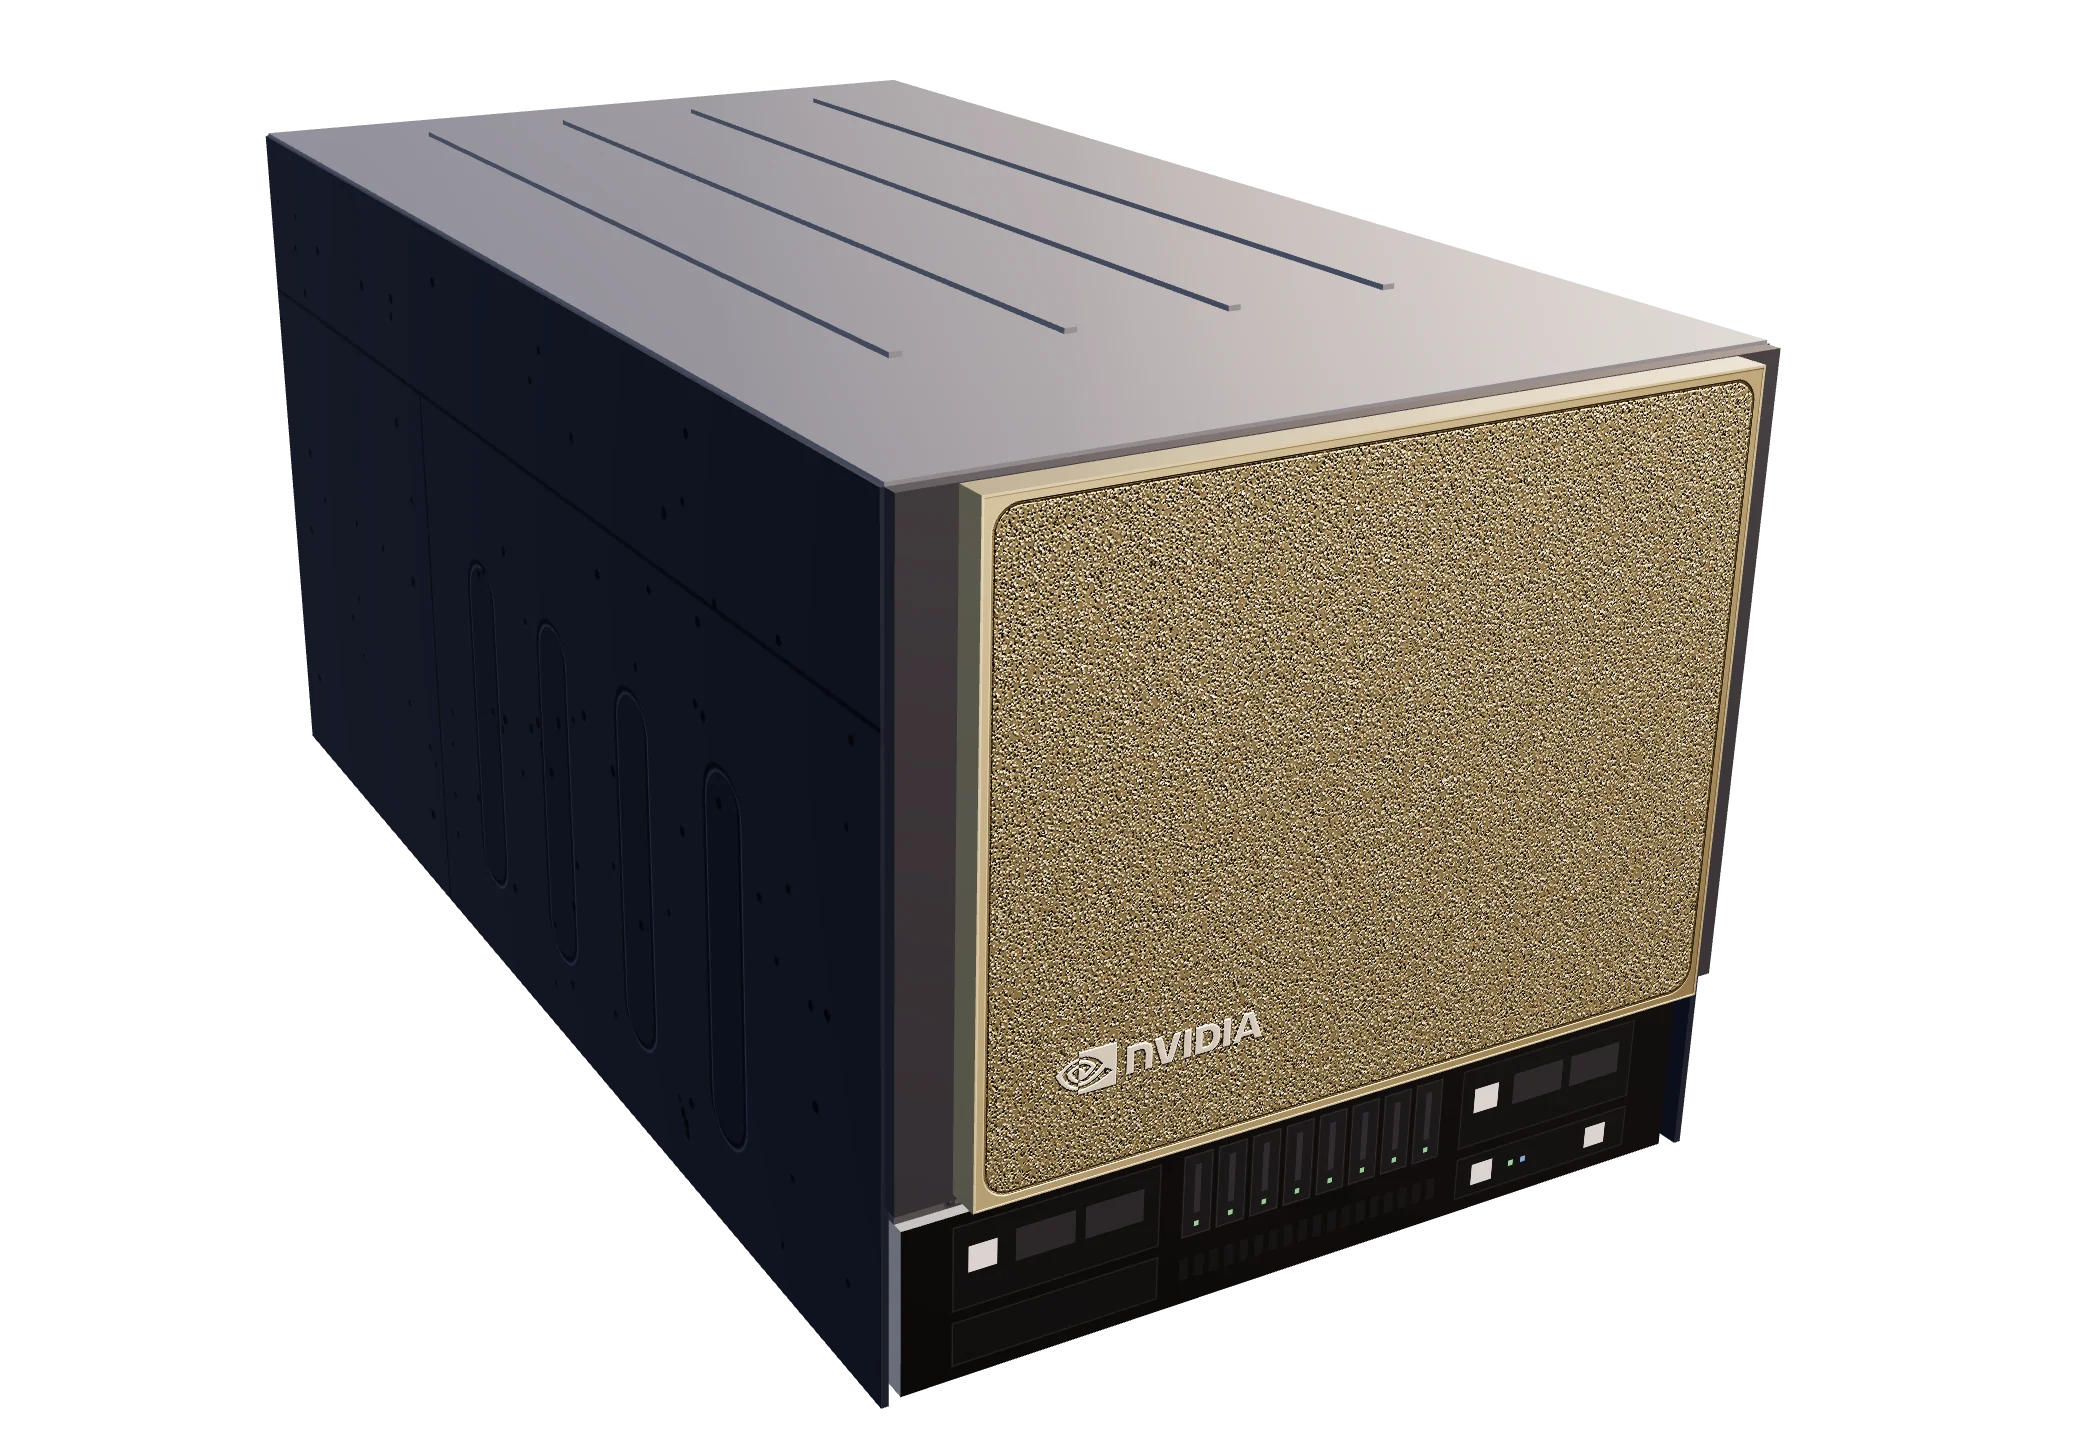
Dedicated nodes
A whole DGX B300, yours alone.
Eight GPUs on one NVLink domain. No neighbors, no preemption.
Request capacityCompute
NVIDIA’s Blackwell Ultra system. Rent a whole one, or start from a single GPU.
Dedicated nodes
Eight GPUs on one NVLink domain. No neighbors, no preemption.
Request capacityOn-demand GPUs
Start from a single GPU and add more when you need them.
Ask about availabilityPer system, as NVIDIA specifies it.
Inside a DGX B300
One GPU tray: two rows of four, two NVLink switches between the rows, and a ConnectX-8 for every GPU.
HBM3e across eight GPUs: about 1.5 times a DGX B200.
Every GPU links to both switches at 1.8 TB/s, 14.4 TB/s in aggregate. GPU-to-GPU traffic stays on NVLink.
Models
Pick a model and see how it fits on one DGX B300.
Platform
Dev machines, batch jobs and monitoring, from the CLI, the console, or your agent.
Monitoring
Utilization, memory, power and temperature for every GPU.
Dev machines
Eight GPUs in VS Code, Cursor, or Jupyter.
Batch jobs
Queue jobs on your reservation. Each one starts as soon as its GPUs are free.
train-1 Sample data
Fabric
1.8 TB/s per GPU over NVLink inside the node, and up to 800 Gb/s per GPU between nodes.
Agent setup
Paste your Arise link into your agent and say what you need. It plans the capacity, you confirm, it builds.
In this demo
DGX B300 · us-west-1
Waiting to start
Console
Everything your agent sets up shows up here too.
your-team · us-west-1
1 serving · private to your-team
| Endpoint | Model | Runs on | Status | Auth | Created by |
|---|---|---|---|---|---|
| kimi-k3 | Kimi K3, one engine | serve-1, 8 GPUs | Serving | Key required | Agent |
curl $ARISE_ENDPOINT/v1/chat/completions \
  -H "Authorization: Bearer $ARISE_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "model": "kimi-k3",
    "messages": [{"role": "user", "content": "Hello"}]
  }'
2 running · 1 queued · 1 completed
| Job | Status | GPUs | Runs on | Progress | Runtime | Submitted by |
|---|---|---|---|---|---|---|
| gemma-4-finetune | Running | 4 | train-1 | 62% · step 18,600 / 30,000 | 5h 41m | CLI |
| gpt-oss-evals | Running | 2 | train-1 | 31% | 22m | CLI |
| v4-pro-batch | Queued | 4 | train-1 | Waiting for 4 GPUs · queued 2 min ago | Not started | Agent |
| gemma-4-evals | Completed | 2 | train-1 | 100% | 47m | Console |
13:52:42  step 17900/30000  loss 1.4291  lr 7.01e-06  1.10 s/step
13:54:32  step 18000/30000  loss 1.4263  lr 6.91e-06  1.10 s/step
13:54:34  checkpoint saved  /vol/gemma-4-finetune/step-18000
13:56:22  step 18100/30000  loss 1.4270  lr 6.81e-06  1.10 s/step
13:58:12  step 18200/30000  loss 1.4222  lr 6.71e-06  1.10 s/step
14:00:02  step 18300/30000  loss 1.4236  lr 6.61e-06  1.10 s/step
14:01:52  step 18400/30000  loss 1.4189  lr 6.51e-06  1.10 s/step
14:03:42  step 18500/30000  loss 1.4174  lr 6.42e-06  1.10 s/step
14:03:44  checkpoint saved  /vol/gemma-4-finetune/step-18500
14:05:32  step 18600/30000  loss 1.4151  lr 6.32e-06  1.10 s/step
Next in queue: v4-pro-batch needs 4 GPUs and starts when they are free.
Open Endpoints to see the API call, or Jobs to see the queue.
Security and compliance
Our security program is built around these standards. Ask for the security package: policies, architecture and controls, under NDA.
Controls for security, availability and confidentiality.
Information security, run as a managed system.
Security in the cloud, and the personal data held there.
Responsible management of AI systems.
A data processing agreement and EU transfer terms.
A business associate agreement for health data.
Roadmap
Customers on DGX B300 get first call on everything we bring online next.
Eight Blackwell Ultra GPUs per system.
72 Blackwell Ultra GPUs per liquid-cooled rack.
The platform after Blackwell.
Power for hundreds of thousands of GPUs.
Existing customers see new capacity before it is listed anywhere else.
The same console, CLI and volumes as you go from one node to many.
You talk to the people who run the hardware.